
How LLM Reasoning Boosts Autonomous Vehicle Safety by 63%: A New RL Framework
We compile, generate and translate using Artificial Intelligence from the below given source. Macro Micro News is responsible for its editorial publication.
Global, Source:
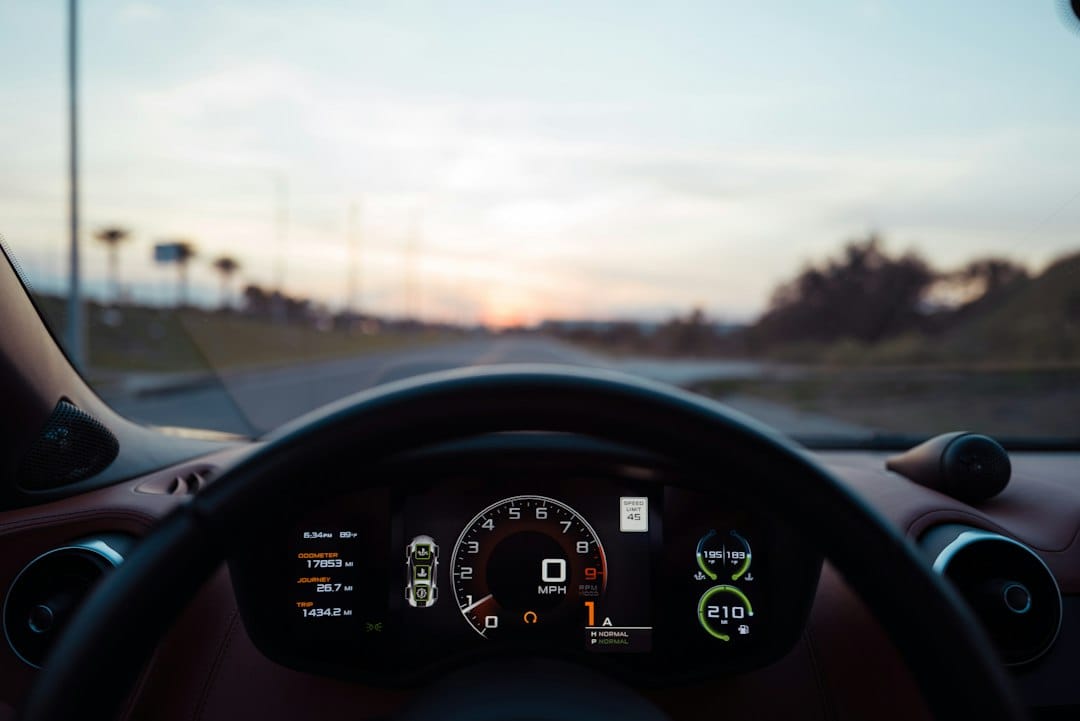
The journey toward fully autonomous vehicles is advancing rapidly, promising a future where roads are safer and traffic flows more efficiently than ever before. Yet, the path to this destination is not without its hurdles. Traditional reinforcement learning models have long been the backbone of decision-making in self-driving cars. These systems learn by interacting with their environment, absorbing vast amounts of data to refine their driving policies. While they excel in controlled scenarios, they often struggle to interpret broader contexts like traffic laws, ethical considerations, or human-like intuition. This gap can lead to unexpected behaviors that compromise safety.
Researchers have now introduced a compelling solution that bridges this divide. By integrating Large Language Model reasoning with reinforcement learning, they have created a hybrid framework that combines the best of both worlds. The system begins with a Vision-Language Model that scans the road ahead, translating visual inputs into detailed natural language descriptions. It notes everything from intersection layouts to pedestrian movements and vehicle speeds. This rich textual context is then fed into an LLM alongside structured prompts containing traffic regulations, defensive driving principles, and historical driving experiences.
The LLM steps in to perform high-level reasoning, generating reference actions that align with human norms and legal requirements. But how do we ensure these suggestions are safe? A multi-layered protection mechanism acts as a safeguard. It validates decisions through backend mapping, logic verification, and strict safety constraints. This process filters out any hallucinations or commands that might be physically impossible for the car to execute. Meanwhile, the reinforcement learning component continues to optimize its policy network by fusing environmental data, ego-vehicle states, and past trajectories.
A dynamic switching mechanism balances the influence of the LLM and the RL agent during training. As the RL agent becomes more proficient, the system gradually reduces its reliance on the LLM. This transition allows the vehicle to maintain robust decision-making capabilities while leveraging the initial guidance provided by the language model. The result is a smoother adaptation to complex driving environments.
Testing this framework on the CARLA simulation platform yielded impressive results. When compared to state-of-the-art algorithms like PPO and SAC, the new approach significantly reduced collision rates by up to 63.1%. It also improved task success rates in dense and complex traffic scenarios. By merging the commonsense reasoning of LLMs with the adaptive learning strengths of reinforcement learning, this technology offers a promising pathway toward reliable end-to-end autonomous driving systems ready for real-world challenges.
Related in Gadgets

Gadgets
Why Your Browser Says No: The Hidden Logic Behind Access Denied Errors
The digital world moves fast. Yet one experience remains universally frustrating for users everywhere. That sudden stop when a website refuses to load. You see the stark message 'Access Denied' or the HTTP 403 Forbidden code. This is not just a random error. It is a critical sig…
Read More...
Gadgets
Why Your Browser Says No: The Hidden Logic Behind Access Denied Errors
Have you ever stared at a blank screen that simply refuses to let you in? That frustrating 'Access Denied' message is more than just a digital roadblock. It is actually a sign that the internet's security systems are working exactly as they should. When you see an HTTP 403 Forbi…
Read More...
Gadgets
COMBI-CBRN: How Modular Sensors Are Redefining Firefighter Safety in CBRN Emergencies
Global, Source Emergency response teams face a complex puzzle when dealing with Chemical, Biological, Radiological, and Nuclear incidents. The safety of first responders often hinges on the accuracy of initial reconnaissance. Traditional methods frequently rely on separate detec…
Read More...
Gadgets
How Structure-Aware Alignment Boosts AI Accuracy in Partial-Label Learning
The world of artificial intelligence faces a persistent hurdle. Perfectly labeled data is rare and expensive to obtain. Researchers have turned to partial-label learning as a solution. This method allows models to learn from ambiguous supervision. Each instance comes with a set…
Read More...
Gadgets
Boost Weed Detection AI Accuracy Without New Hardware: The MASC Method
Agricultural technology is experiencing a major shift as artificial intelligence models grow more resilient to environmental changes. A new study introduces Metadata-Guided Appearance-Shift Consistency (MASC), a training framework that improves weed detection in outdoor images w…
Read More...
Gadgets
AI Detects Transmission Tower Flaws: 59% Precision Boost for Grid Safety
Modern energy grids depend on the reliability of electrical transmission infrastructure. Manual inspections of towering steel structures remain labor-intensive and prone to human error. A recent breakthrough in computer vision technology offers a transformative solution for iden…
Read More...
Gadgets
How Fault-Aware HIL Verification Secures AUTOSAR Timing Compliance in Modern ECUs
As automotive electronics grow more complex, ensuring the safety integrity of Electronic Control Units (ECUs) has become a top priority under standards like ISO 26262. While functional correctness is routinely validated, timing correctness remains a nuanced challenge. This is es…
Read More...
Gadgets
Why You Are Blocked: The Hidden Mechanics of Web Access Control
Have you ever stared at a screen and seen those three ominous words: Access Denied? It is not just a technical glitch. It is the result of sophisticated security protocols working hard to protect server resources and sensitive data. This phenomenon is a fundamental aspect of how…
Read More...
Gadgets
Class-D Amplifier Limits: Why Switching Frequency Defines Your Audio Fidelity
Class-D amplifiers have long been celebrated for their impressive energy efficiency. Yet achieving pristine audio quality requires navigating a complex web of technical constraints. A recent study in Electronics (MDPI) offers a new framework for selecting the optimal switching f…
Read More...
Gadgets
Why Your Greenhouse Sensors Fail: The MQTT Timing Trap and How to Fix It
Smart greenhouses promise precision agriculture through continuous data streams. Yet many growers face a frustrating reality where wireless sensor networks falter under the weight of their own complexity. A recent study in Electronics (MDPI) sheds light on this issue by introduc…
Read More...